Post-Mortem Design for AI-Assisted Operations
Organizations must audit workflow defects before blaming the model for failure.
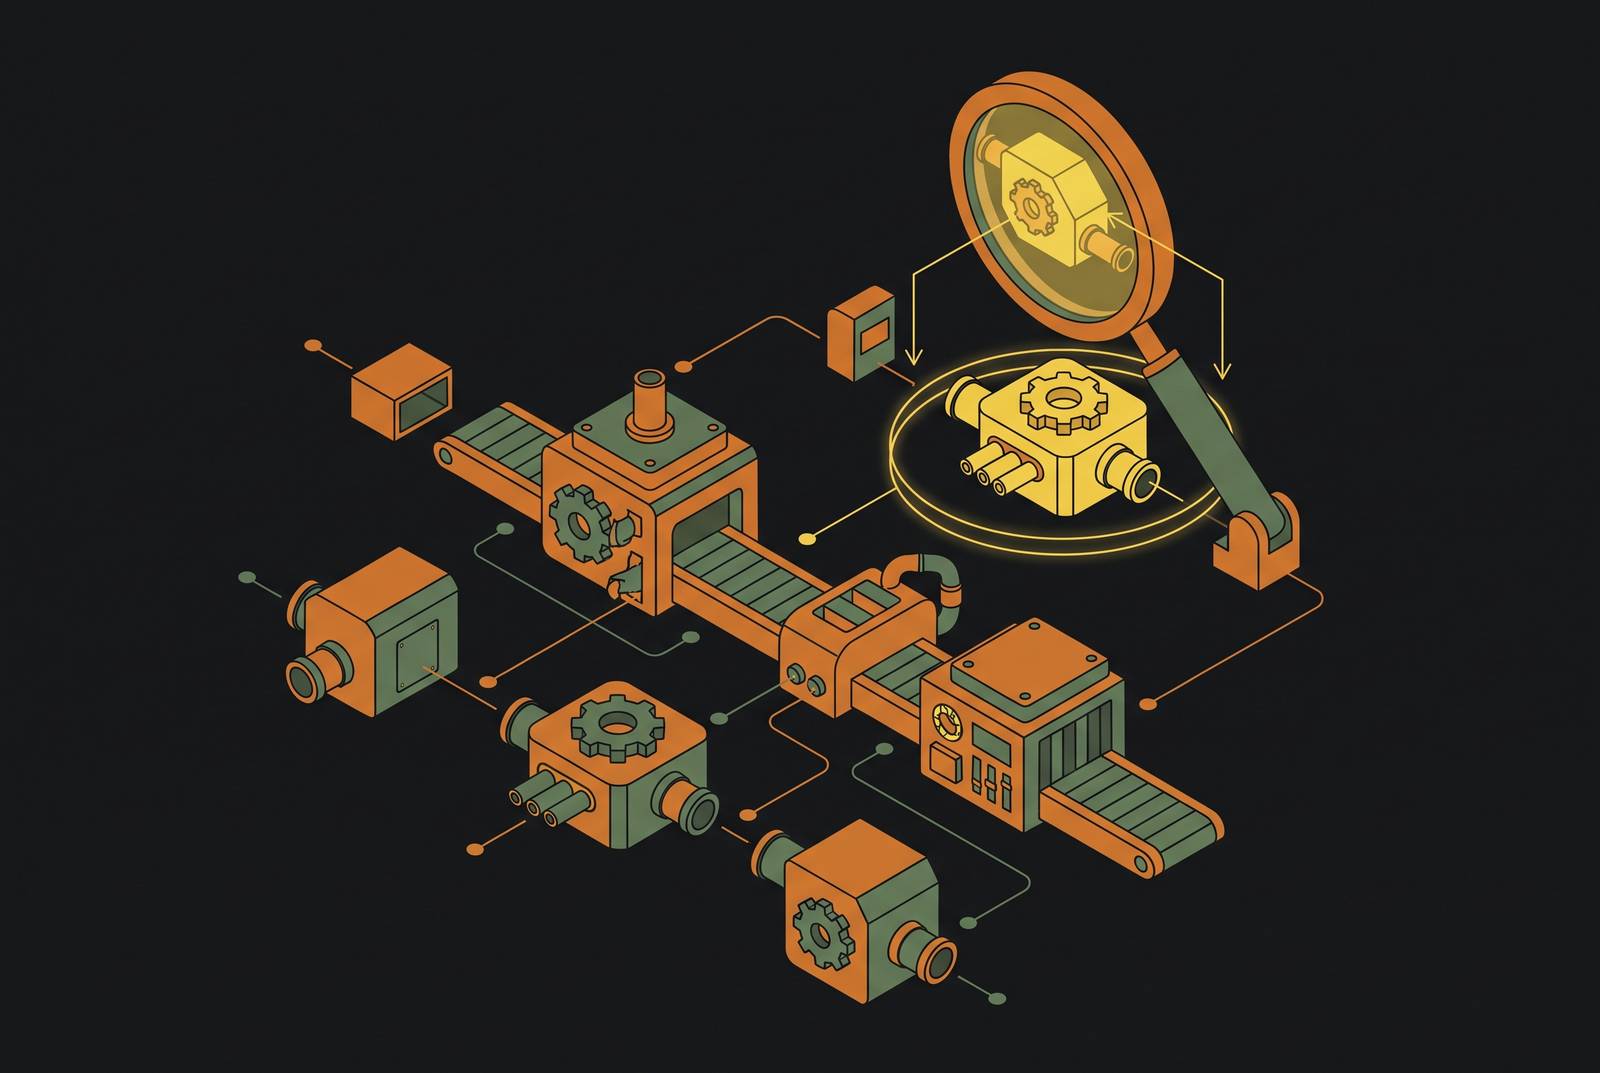
A post-mortem for AI-assisted operations must explain more than why an agent failed. It must establish what was broken in the process before the agent arrived. Effective post-mortem design traces the failure back to those conditions, distinguishes model behavior from workflow defects, and identifies what must change before redeployment. Otherwise, teams keep improving models while leaving what caused the failure in place.
Why AI agents fail in operations before the model is ever the problem
The blame-the-model reflex starts with the prompt, the output, and the confidence threshold. These are visible parts of an AI failure, so they become the focus of the investigation. But the break point may sit upstream, in the workflow the agent was handed. When data is fragmented, hand-offs are implicit, or ownership is unclear, an agent can accelerate dysfunction. The output exposes the defect without explaining its origin.
Deloitte's 2026 manufacturing survey shows that most manufacturers have proven AI can work, while only a small fraction have scaled it successfully. Adoption is strongest in Quality, Production, and Logistics/Supply Chain, where process signals are rich, outcomes are measurable, and operational ownership is clear. That pattern suggests that organizations struggle to put models to work even when the models can do the job. A useful post-mortem therefore treats the model as one part of the system under investigation.
What a post-mortem for AI-assisted operations is actually supposed to do
An incident review can produce a complete timeline and still leave the team unable to explain why the failure occurred. Conclusions such as “the model got it wrong” or “the prompt was bad” name a symptom and close the case. Conventional post-mortems ask what broke, when it broke, and how to prevent recurrence. Those questions remain necessary, but they do not automatically expose defects in process design. For AI-assisted operations, the investigation must also establish whether the agent was asked to compensate for conditions it could not fix.
The post-mortem is therefore an account of the relationship between the agent's behavior and the workflow that made that behavior possible. Its purpose is not merely to audit the AI, but to surface the conditions that made failure structurally inevitable. This changes the document itself. A failure timeline must be paired with evidence about the process at deployment. Without that evidence, the review cannot tell whether the agent caused an error or exposed a flaw that was already there.
The regulatory audit analogy clarifies the distinction. An organization may demonstrate that policies exist while struggling to produce consistent evidence that people execute them. Tasks remain unassigned and evidence remains scattered because the policy is disconnected from daily work. Looking only at model configuration can miss the same gap between how the work should run and how it does run. Although the objection that a process audit takes too much time after every incident is reasonable, the audit is the mechanism for stopping the same defect from recurring under a different agent.
How to trace an AI failure backward to its process origin
The diagnostic task is to move backward from the failed action to the conditions on which that action depended. The post-mortem must establish what information the agent used, which workflow it followed, what authority it held, and what recovery path existed. Each answer points to a different kind of fix. The recurring failure modes provide a way to test the evidence.
For data illegibility, the central question is where the data schema diverged from operational reality and when that divergence stopped being noticed. A process may generate abundant data while leaving it fragmented across systems, untrusted, or schema-inconsistent. The agent then produces an output from inputs that were already wrong. The investigation must distinguish the agent's handling of information from the quality and meaning of the information it received.
For process illegibility, the question is what the documentation said compared with what people actually did. Informal hand-offs and implicit approvals can carry decisions that never appear in the written workflow. An agent given that written version inherits the gap between description and practice. For scope mismatch, the question changes to what the agent needed to observe, coordinate, or verify but could not access. What the agent needed may have been in another system, another agent, or a person's head, beyond the authority boundary set for the task.
Multi-agent orchestration makes that boundary especially important because a coordination failure cannot be explained solely by inspecting each agent's output. The investigation must establish which dependencies the workflow required the agents to manage. For a governance gap, it must then identify the recovery path for a condition outside the agent's design envelope. That means examining whether escalation was defined, state persisted across hand-offs, and a human checkpoint existed for edge cases. If nobody owned recovery, the diagnosis must cover how the process ran as well as how the agent responded.
What the process looked like before the agent arrived — the pre-deployment audit as post-mortem evidence
A review without a pre-deployment baseline can describe what broke, but it lacks the comparison needed to judge causation. AI may have caused the problem, revealed it, or simply been present when it surfaced, and the review cannot reliably distinguish these possibilities. The pre-deployment audit supplies that comparison. It records how the process actually worked before the agent. Its value lies in evidence.
That evidence includes actual hand-offs, the provenance of every input the agent will consume, and the human decisions the agent is replacing or assisting. It also records which steps were manual and why. Just as importantly, it defines failure in the manual process, including missed hand-offs, delayed decisions, and stale data. An existing failure pattern changes the interpretation of an incident after deployment. Without that baseline, the post-mortem can wrongly assign the whole failure to the newest participant in the workflow.
Deloitte's 2026 manufacturing survey identifies data availability and quality as a leading implementation barrier, cited by 30% of respondents. A pre-deployment audit gives the incident review evidence of how that data concern plays out in a given process. Job sites generate operational data through computer vision, IoT sensors, and geofencing, but the relevant question is whether that data is trusted enough to run the job. Discovering after deployment that it was untrustworthy identifies a pre-existing condition.
Moving quickly is a legitimate constraint, and the answer to a missing baseline is not simply that the team should have slowed down. The post-mortem now has to reconstruct the missing pre-deployment comparison, work that is harder and more expensive after failure because that comparison was never established. The review must record the missing audit as a finding because its absence makes the same failure modes harder to spot in the next deployment. Otherwise, the review substitutes competing accounts of responsibility for evidence about the process.
The structural elements a post-mortem template for AI-assisted operations must include
The template should function as a framework for diagnosis. Its value is in the questions it forces the team to answer. Each part must connect the incident to the process in which it occurred. Microsoft's 2026 manufacturing analysis identifies auditability as a core requirement for scaling AI. A post-mortem supports that requirement when it makes the relationship between deployment conditions, agent behavior, and corrective action explicit.
Section 1 establishes the process state at deployment. It records the workflow, hand-offs, ownership of each step, and data quality baseline, with any missing evidence treated as a finding. Section 2 defines agent scope and authority, including what the agent could decide, trigger, or execute without human review. It also establishes which conditions fell outside that envelope and what happened when the agent encountered them. Together, these sections separate the process the team had from the authority it gave the agent.
Section 3 provides the failure timeline with process annotations. Each event is checked against the pre-deployment process map so that known hand-off risk, a data quality boundary, or a governance gap stays in view. Section 4 classifies the root cause using the evidence for data illegibility, process illegibility, scope mismatch, or a governance gap. The classification must produce a diagnosis rather than an undifferentiated collection of contributing factors. The classification must explain which condition in the process made the failure possible and therefore what the repair must fix.
Section 6 records the audit requirements for the next deployment, specifying what must be documented before another agent goes live. Those requirements preserve a baseline, but they do not replace the decision at the heart of the current review. Section 5, the process redesign recommendation, states what must change in the underlying workflow before redeployment. Teams most need this and too often skip it, because adjusting a prompt or retraining a model is not a substitute for deciding how the work itself must change.
Why blaming the model is operationally expensive, not just intellectually wrong
Ignoring where the failure began in the process means spending money on the same risk in the next deployment. A team can improve the model and still return it to fragmented data, informal hand-offs, or unowned exceptions. The technical change then leaves the causal condition untouched. This is one mechanism behind the pilot trap, where demonstrations establish that AI can work but deployment practices cannot turn that promise into consistent operation. The expense is not just another incident, but another cycle of work that fails to address its cause.
In a multi-agent workflow, the same mistake can spread responsibility without improving the diagnosis. A review focused on the model looks at each agent while leaving the coordination design as it is. The defect can then recur at the next coordination point, involving a different agent and a different team. Repeated failures also erode organizational credibility, leading operations leaders to lose confidence in AI deployment generally even though the process design is at fault. That loss is harder to recover than a technical fix.
Deloitte's 2026 survey shows that operational disruption risk is cited by 79% of respondents as a top concern. Improving the model alone does not fix disruption caused by unclear ownership or a missing recovery path. Those risks require a legible process and correctly bounded agent scope. A post-mortem that fails to make that distinction directs spending toward the visible component while leaving the operational exposure in place.
Building post-mortem discipline into AI deployments from the start, not after the first failure
The baseline, authority boundaries, and recovery paths needed for a useful review belong in the deployment from the start. The 2026 AI and ML for Smart Manufacturing roadmap names the need for trustworthy, explainable, and reliable operation in high-stakes industrial environments as a major challenge. Meeting that challenge depends on the system in which the model operates, including its surrounding process. A review built around that system can yield process intelligence as well as an incident report.
Before deployment, the work is to audit the process, document hand-offs, establish the data quality baseline, and define agent scope and escalation paths. During deployment, monitoring must include agent outputs and process signals such as hand-off completion rates, data freshness, and exception escalation frequency. After failure, the review uses that evidence to classify the failure mode and recommend redesign before redeployment. Successful deployments warrant the same examination. Their favorable process conditions are evidence that can guide the next deployment.
The work begins with a specific, painful process. Showing how that process runs today, where it hurts, and what an agent would be asked to compensate for creates the first usable template. The same work reveals what needs to be rebuilt before automation and what evidence later reviews will need. That is the prospective audit framing at the center of effective post-mortem design. The best post-mortem is the one run before deployment, while its findings can still change the process the agent will inherit.